A cloud provider may sell digital capacity, but the business is physical long before a customer runs a workload. Power, cooling, network capacity and scarce servers must be secured. Customer commitments have to match equipment orders that can reach into the millions of dollars.
Compute USA was created to manage those dependencies for enterprises, AI labs and other large buyers. Launched in May 2026, the U.S.-based AI infrastructure company provides access to high-performance graphics processing units, or GPUs, through server sales, long-term capacity agreements, compute trading, architecture and deployment services. The model gives customers several ways to procure hardware, secure capacity and manage infrastructure after installation.
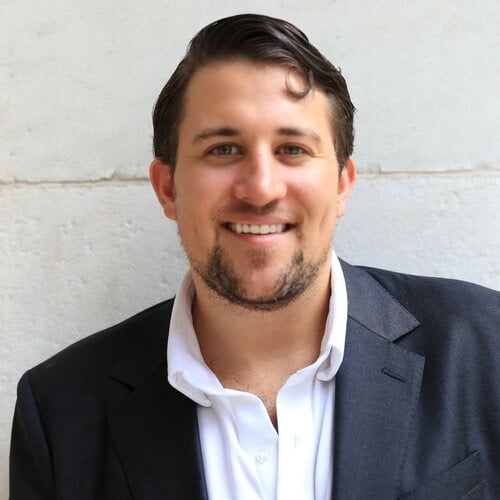
Founder and CEO Mason Jappa brings more than a decade of experience building and scaling infrastructure businesses where technology, energy, and high-performance computing converge. As a serial entrepreneur and industry leader, Jappa deployed large-scale digital infrastructure across North America and has built strategic partnerships with some of the world’s leading technology and data center organizations.
Jappa believes the company operates best when those decisions stay connected. Access to capital impacts what Compute USA can buy, while hiring helps determine how well it can deliver.
“Most weeks, [my schedule] is split across a handful of consistent priorities: capital and investor conversations, since we’re scaling fast and access to capital is a constraint; key hiring and org-building, because the team is growing quickly and every senior hire matters disproportionately at this stage; customer and partner conversations, since deployments of this size take real relationship-building; and staying close enough to the technical roadmap and vendor relationships that I’m not making capital allocation decisions in the abstract,” Jappa said. “It’s a lot of context-switching by design. Early-stage infrastructure companies don’t really have a ‘typical’ week.”
Those responsibilities may occupy separate blocks on Jappa’s calendar, but they do not stay separate inside the business, he explained. Customer commitments, hardware availability and financing decisions all impact one another, creating the operating flow Compute USA uses to scale.
Compute USA Puts Capital, Customers and Technical Detail in the Same Room
The four priorities Mason Jappa described form a chain of operating constraints. Hardware allocation can become a financing decision; a site’s power availability can determine which customer timeline is realistic. A change in GPU architecture can alter an agreement’s economics before deployment.
That approach reaches back to Jappa’s years in enterprise technology consulting and finance, where he saw how large organizations plan for disruption and deliver technology for clients that measure reliability as closely as innovation.
“Those years gave me a grounding in how large, risk-sensitive organizations actually make decisions,” Jappa said. “At Fusion Risk Management, I was close to how enterprises think about operational risk and business continuity, the kind of discipline that assumes things will break and plans for it in advance rather than reacting after the fact. Infosys exposed me to the realities of delivering technology at scale for demanding clients, where execution and reliability matter as much as the underlying technology itself.”
He carried that information into Compute USA. The company sells and procures enterprise servers, structures agreements intended to lock in capacity, operates a compute trading desk, and works on architecture and deployment. Those functions require coordination across the useful life of the infrastructure.
“What I carried forward into Blockware and now Compute USA is a bias toward building infrastructure that’s resilient and auditable from day one, not bolted on later,” Jappa explained, “treating uptime, risk and operational rigor as product features, not afterthoughts.”
Why Constant Context-Switching Can Be a Form of Control
At a young company, focus can mean knowing which subjects cannot be separated. Jappa’s involvement is intended to keep a technical choice connected to its financial consequences and a sales commitment grounded in what suppliers and sites can support.
The same logic influences which investors and strategic partners enter the picture. Compute infrastructure is capital-intensive, but money does not resolve every constraint. A useful partner can improve access to a powered site, scarce hardware or customers.
“Capital is largely fungible at this stage of the market,” Jappa said. “What isn’t fungible is whether a partner actually understands the category and can help us move faster on the things that are hard to buy: access to power and sites, hardware allocation, and customer relationships. I look for partners who bring real domain expertise in compute, energy or data center infrastructure, who move at the speed this market requires, and who are aligned on a multiyear build rather than looking for a quick markup.”
That standard creates a practical test for alignment, he said. A partner’s value rests on whether the relationship reduces friction elsewhere in the system. It also favors patience, since data center capacity and hardware supply can move on different clocks than customer demand.
Compute USA Hires for Judgment Before a Job Description Goes Stale
Hiring presents a different version of the same problem. The neocloud segment, built around high-performance GPU access for AI and other demanding workloads, is new enough that few candidates have spent a long career inside a company built exactly like Compute USA. Familiarity with established systems may matter less than the ability to create one.
CEO Mason Jappa looks for evidence that a candidate has carried responsibility without a complete map, whether building a function from scratch or making a costly decision with limited data.
“When the category is new, resumes matter less than pattern-matching for people who can operate in ambiguity and have already proven they can build something from a standing start,” Jappa said. “I look for people who’ve had to make real decisions with incomplete information rather than people who’ve only operated inside well-defined roles at mature companies. In a market like GPU and neocloud infrastructure that didn’t exist in its current form a few years ago, the playbook is being written in real time, so I’d rather hire for judgment and resourcefulness than for a resume that matches a job description that’s already out of date.”
That mindset raises the stakes of early hiring. He says employees influence how decisions are communicated, what level of risk is tolerated and whether urgency becomes disciplined speed or simple haste.
“Culture gets set in the first handful of hires far more than people expect, and it gets tested every time you scale headcount quickly, which we’ve had to do at Compute USA given how fast this market is moving,” Jappa said. “I try to protect it by keeping the hiring bar high even under pressure to move fast, being direct about what we value early with new hires rather than assuming it osmoses over time, and staying accessible enough as the team grows that people aren’t guessing at how leadership thinks. The throughline is that I’d rather grow slightly slower than let the bar slip on who we bring in.”
Accessibility matters because a fast-growing team constantly encounters decisions with no settled precedent. He believes employees need exposure to leadership’s reasoning so they can apply the company’s values when no one is available to approve the next step.
Shared judgment then becomes a form of operating leverage.
The Operating Throughline Runs Through Power, Space and Hardware
Compute USA is entering a market crowded with new terminology, but its work comes down to tangible assets and finite resources. Servers occupy space, cooling and electrical systems have limits, and vendor relationships affect delivery.
Jappa sees continuity between his earlier work in Bitcoin mining infrastructure and the AI systems Compute USA is building. The customers differ, but many operating questions are familiar.
“Both businesses are fundamentally about the same thing: acquiring and operating physical infrastructure (power, space, cooling, hardware) better and faster than the market expects, in service of a compute-hungry demand curve,” he said. “The specific technology changes, but the operational playbook carries over almost entirely: securing power and sites early, building relationships with hardware vendors, and running lean, disciplined operations at scale.”
The U.S. focus adds another consideration. Compute USA positions domestic control of AI infrastructure as a strategic issue. Jappa’s experience across consulting, mining and compute convinced him that dependency risk extends beyond any single piece of hardware.
“I’ve seen firsthand how much of the world’s critical digital infrastructure depends on supply chains and dependencies that aren’t fully within any one country’s control,” he shared. “That experience is a big part of why Compute USA is built around U.S.-based deployment. GPU compute is becoming the kind of strategic infrastructure that countries will increasingly want built, powered and controlled domestically, not dependent on infrastructure or capacity sitting outside their borders.”
For Compute USA, the work after an agreement is signed is the clearest test of its operating model. Each deployment must turn access to capital, power and hardware into reliable capacity while the organization keeps its hiring bar and customer commitments intact. In an unsettled market, the next contract will depend in part on how well the last one was executed.